The short answer
Agentic DevOps uses AI agents to interpret operational context, propose work and invoke tools that provision infrastructure, deploy software or investigate failures. A useful implementation combines those agents with deterministic checks, scoped permissions and accountable people. The agent coordinates work; the delivery system enforces what can happen.
What to take away
- Start with one bounded workflow and a measurable outcome.
- Keep policy enforcement in the tools that execute changes.
- Record the request, approved change, execution and verification together.
How does agentic DevOps work?
A conventional pipeline follows a predefined sequence when a trigger fires. An agent can choose a next step from available tools after inspecting a request and the current environment. It might discover that a deployment needs a queue, ask for a missing decision, or investigate why a release failed. The execution path can vary while the underlying deployment controls remain predictable.
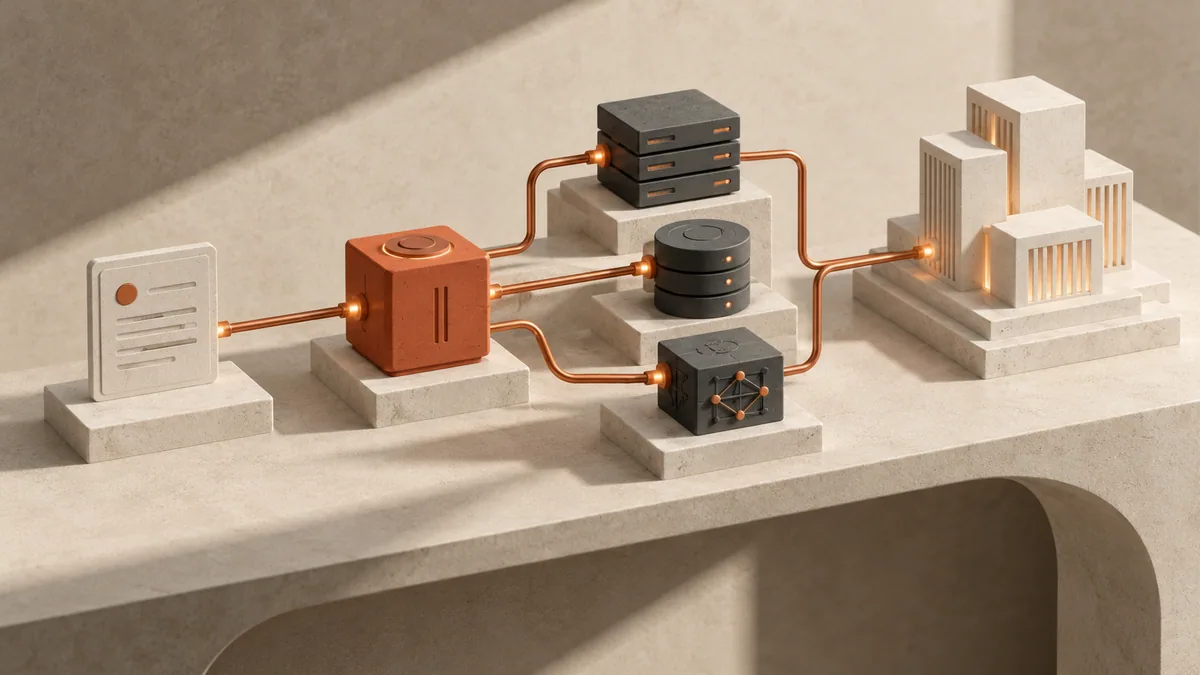
For example, a team asks for a staging environment for a new document-processing service. The agent gathers the service requirements, selects an approved template and submits a provisioning request. The platform validates the environment, permissions and resource limits, then creates resources. A deployment runs against the resulting environment and reports health checks. That sequence has observable outputs at every boundary.
Reference: source 1
Agentic DevOps, CI/CD and infrastructure as code
These approaches work together. CI/CD provides a repeatable release mechanism. Infrastructure as code describes resources in a reviewable form. An agent can gather inputs and coordinate both. Replacing either foundation with a conversational transcript makes recovery and change review harder.
| Layer | Useful responsibility | Evidence to keep |
|---|---|---|
| Agent | Interpret the request and coordinate tools | Request, assumptions and tool results |
| CI/CD | Build, check and release a known artifact | Commit, artifact and deployment result |
| Infrastructure as code | Describe and reconcile cloud resources | Reviewed plan and resulting state |
| People | Own risk decisions and incident response | Approval and escalation ownership |
Where should a team start?
Choose work with a clear input, limited scope and an obvious success condition. Creating a temporary test environment or collecting deployment diagnostics is easier to evaluate than giving an agent responsibility for every production incident. Agree what should happen when the task fails before running the successful path.
A good first workflow returns a resource inventory, an environment URL, a test result and an expiry time. A failed run returns a precise error and identifies any resources left behind. Measure time to a usable environment and cleanup success, rather than the number of tool calls or the apparent fluency of the agent.
- Write down one request and its acceptance criteria.
- Give the executor access to one isolated environment.
- Exercise success, rejection, timeout and repeated-request cases.
- Review the evidence before expanding permissions or scope.
Which guardrails matter most?
The execution service should check identity, target environment, allowed resource types and current policy. A prompt saying that production is off limits is insufficient if the connected credentials can still modify it. Separate observation from mutation so an investigation can remain useful with narrower access.
Treat tool output and repository text as information that may be wrong or adversarial. A log message cannot grant deployment approval. An incident ticket cannot expand a role. Bind approval to the specific operation and state it covers, then re-evaluate when the proposed change changes.
Reference: source 2
Where does Latifold fit?
Latifold is designed as an infrastructure control plane for existing coding agents, with MCP and API as first-class interfaces. AWS, Azure and Google Cloud are supported: begin with read-only discovery, then add narrowly scoped write access for supported operations. Humans set authority and approval rules. Existing IaC ownership remains authoritative, and the team still owns application incidents. Confirm operation coverage when evaluating the product.
The first useful conversation is about your existing delivery process: where work gets stuck, what evidence is missing and which infrastructure decisions still need an experienced engineer. Automate that bounded gap, then expand from measured results.
Common questions
Does agentic DevOps replace a DevOps engineer?
It can reduce coordination and repetitive execution work. Architecture decisions, production risk, incident ownership and exceptions still need an accountable owner. The staffing effect depends on the workflows delegated and the support arrangement.
Do I need MCP to use agentic DevOps?
No. Agents can use APIs and other tool interfaces. MCP provides a standard way to expose tools and context to compatible hosts; the deployment and permission controls still need to be implemented behind that interface.
Sources & context
References checked on 18 October 2026. Implementation recommendations and illustrative examples are Latifold editorial guidance.
- Model Context Protocol: architecture overview
The protocol's host, client, server and tool model; the workflow recommendations here are Latifold's guidance.
- OWASP: LLM prompt injection prevention
Background on untrusted inputs and boundaries around tool use.
Prepared with AI assistance for Latifold. Verify technical details against your environment and the linked documentation. See our editorial approach.